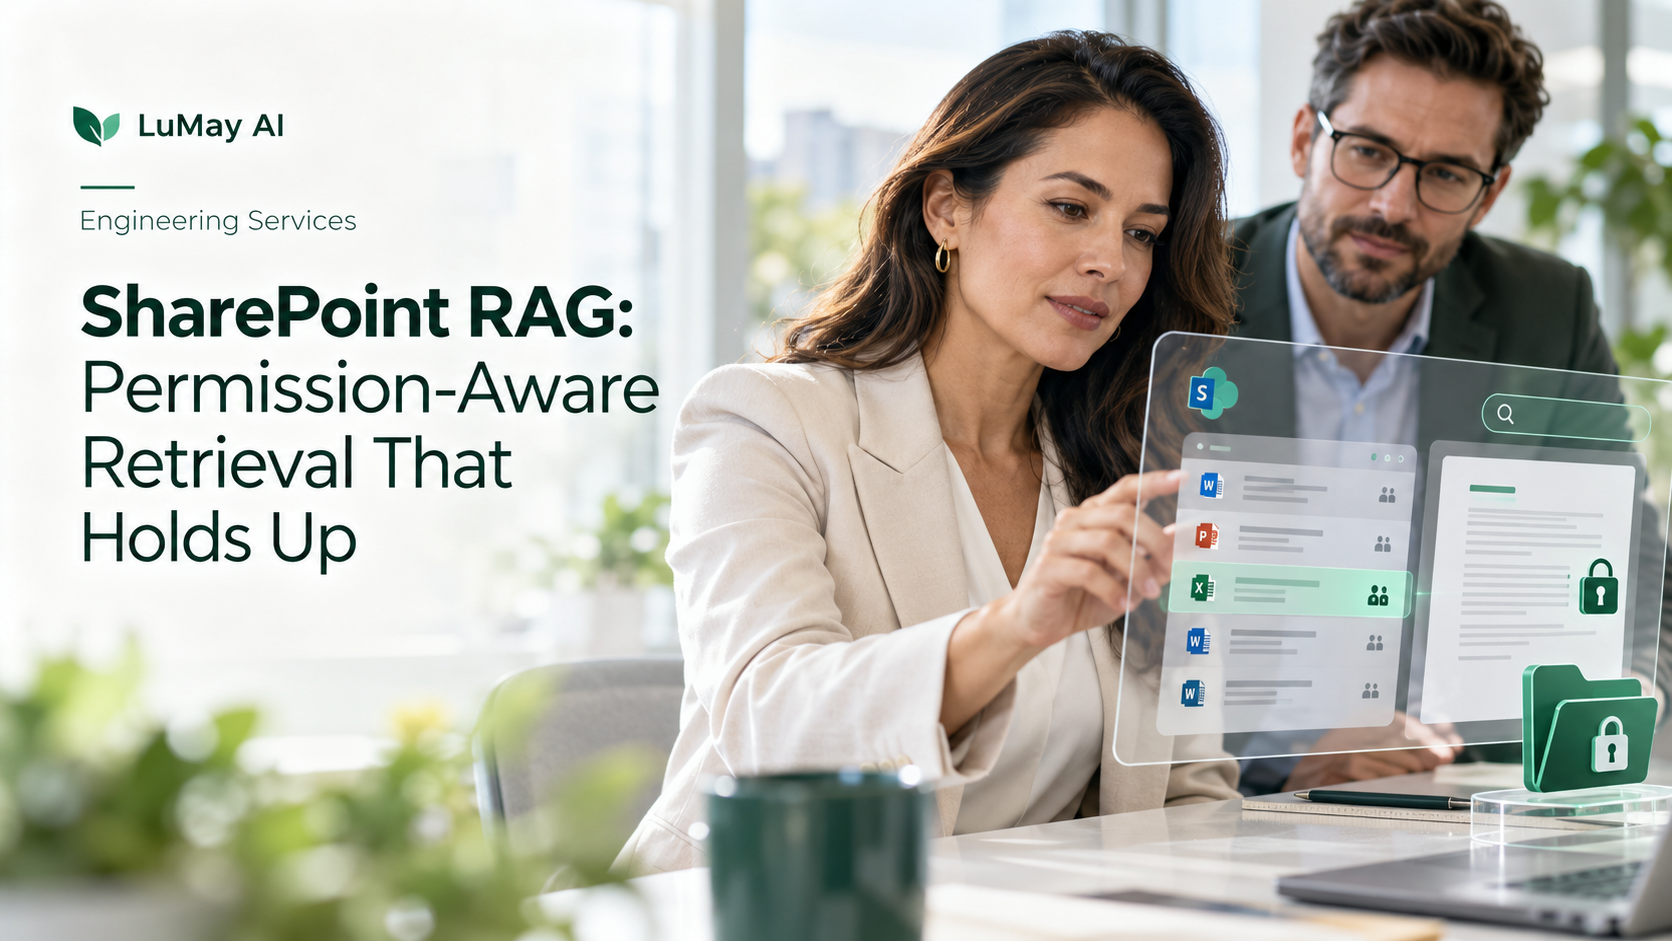
SharePoint RAG is retrieval-augmented generation that answers questions from SharePoint content. The hard requirement is permission awareness: every retrieved passage must be one the asking user could open in SharePoint themselves.
There are three ways to get there: a security-trimmed retrieval API, a search index with native ACL enforcement, or your own index with permissions copied in as filter fields. Each handles permission changes differently.
This guide compares the options, explains the stale-permission problem, gives a worked access-test plan and lists what to check before launch.
Why Permissions Are the First Design Decision
A RAG assistant that ignores SharePoint permissions can quote a confidential HR file to anyone who asks. Filtering after generation is too late, because the model has already seen the text.
Authorization has to run before passages reach the model. That means the retriever must know who is asking and what they may read, at query time.
• Identity: the user's Microsoft Entra ID identity and group memberships
• Document permissions: effective access on each file, including inherited and shared links
• Enforcement point: the retriever, not the prompt or the user interface
Three Architecture Options
| Option | How permissions are enforced | Strength | Watch for |
|---|---|---|---|
| Option A: Microsoft 365 Copilot Retrieval API | Service trims results to the signed-in user via a delegated token | No index or ACL sync to build | Licensing, delegated-only access, less control over chunking |
| Option B: Azure AI Search with SharePoint ACLs | Indexer pulls permission metadata; query token checked against it | Native identity-based filtering | Preview features; confirm supported content and principals |
| Option C: Custom index with ACL fields | Ingestion writes allowed users and groups per chunk; queries filter on them | Works with any vector store | You own sync, staleness and group expansion |
Microsoft documents the Retrieval API as security trimming content for the calling user, with Files.Read.All and Sites.Read.All as the least-privileged delegated permissions. Application permissions are not supported for it.
Step 1: Inventory Sites and Sensitivity
List the sites, libraries and content types in scope. Mark which hold sensitive material such as HR, legal or finance documents. Start with a narrow, low-sensitivity scope for the pilot.
If you use Option C, Microsoft's engineering team recommends the Graph Sites.Selected permission so the ingestion app has no default access and each site is granted explicitly.
Step 2: Resolve Effective Permissions
Effective access is not just a list on the file. It includes inheritance from the site and library, SharePoint groups, Entra ID groups and sharing links.
• Normalize users and groups to stable Entra ID object IDs
• Decide how to treat sharing links such as "anyone in the organization"
• Expand or store groups consistently, and document which you chose
Step 3: Handle Stale Permissions
When permissions are copied into an index, a change in SharePoint does not reach the index until the next sync. A user whose access was revoked may still retrieve that content in the gap.
Microsoft's guidance suggests scheduled re-ingestion, webhooks to trigger updates on change, shorter intervals for sensitive content, and telling stakeholders the expected delay. Write that delay into your security sign-off.
Step 4: Chunk, Embed and Keep the Link to the Source
Every chunk should carry its source URL, document ID, version and permission fields. That lets the assistant cite sources and lets you remove chunks when a document is deleted.
Chunking choices affect answer quality more than model choice in many systems. See our RAG chunking strategies guide for options.
Worked Example: An Access Test Plan
Illustrative example: a hypothetical test design, not a customer project. A policy assistant indexes three sites: Company Policies (all staff), HR Casework (HR group only) and Finance Close (finance group only).
| Test case | User | Query | Expected result |
|---|---|---|---|
| T1: Allowed read | Any employee | "What is the travel policy?" | Answer cites Company Policies |
| T2: Blocked site | Sales employee | "Summarize open HR cases" | No HR content; assistant says it found nothing it can share |
| T3: Group member | HR analyst | "Summarize open HR cases" | Answer cites HR Casework |
| T4: Revoked access | HR analyst removed from group | Same query after sync window | No HR content |
| T5: Shared link | User with a direct link to one finance file | Query about that file | Behavior matches documented sharing-link policy |
| T6: Deleted file | Any employee | Query about a deleted policy | No answer from the deleted file after sync |
Run T4 twice: once inside the sync window and once after it. The first run documents your real exposure window; the second confirms the sync works.
Pre-Launch Checklist
• Retrieval enforces permissions before passages reach the model
• Ingestion uses least-privileged Graph permissions
• Effective permissions include inheritance, groups and sharing links
• Sync interval and exposure window are documented and accepted by security
• Every chunk has source URL, document ID, version and permission fields
• Deleted and moved files are removed from the index on schedule
• Access tests T1 to T6 pass and are re-run after each pipeline change
• Answer quality is measured separately from access, as in our guide on how to evaluate a RAG system
Common Mistakes to Avoid
• Using an app-only identity at query time: the retriever must act for the user, not for a service account with access to everything
• Indexing before cleanup: over-shared sites become over-shared answers
• Dropping permission fields from chunks: a chunk without ACL data cannot be filtered
• Testing only happy paths: revoked users, guests and sharing links are where leaks appear
• Caching answers across users: a cached answer for one user may contain content another cannot see
Questions to Ask Any RAG Partner
• Where exactly are permissions enforced, and can we see the code path?
• What is the sync interval and exposure window for permission changes?
• How are sharing links and guest users handled?
• Which access tests run automatically after each pipeline change?
How We Evaluated This Guidance
We reviewed current vendor and standards documentation listed under Sources, read on October 31, 2026, and compared it with the pages ranking for this topic. We did not run benchmarks; figures marked Illustrative example are assumptions, not results.
Limitations
Several Azure AI Search permission features are documented as preview; check current status and support before committing. The Retrieval API depends on Microsoft 365 Copilot licensing, which this guide does not assess.
No option removes the need for good SharePoint hygiene. If permissions in SharePoint are too broad, a permission-aware assistant will faithfully expose that over-sharing.
Our own product (disclosure: LuMay sells this). LuMay's RAG development services page describes connecting AI applications to SharePoint and other sources and enforcing authentication and permissions during retrieval. The connectors page lists SharePoint and OneDrive through Microsoft Graph. This is not a ranking.
Next Step
If you are planning an assistant over SharePoint, start with the site inventory and access test plan. Discuss a permission-aware RAG build with LuMay's RAG engineering team.
Sources
• Microsoft Learn: Microsoft 365 Copilot Retrieval API
• Microsoft Learn: Document-level access control in Azure AI Search