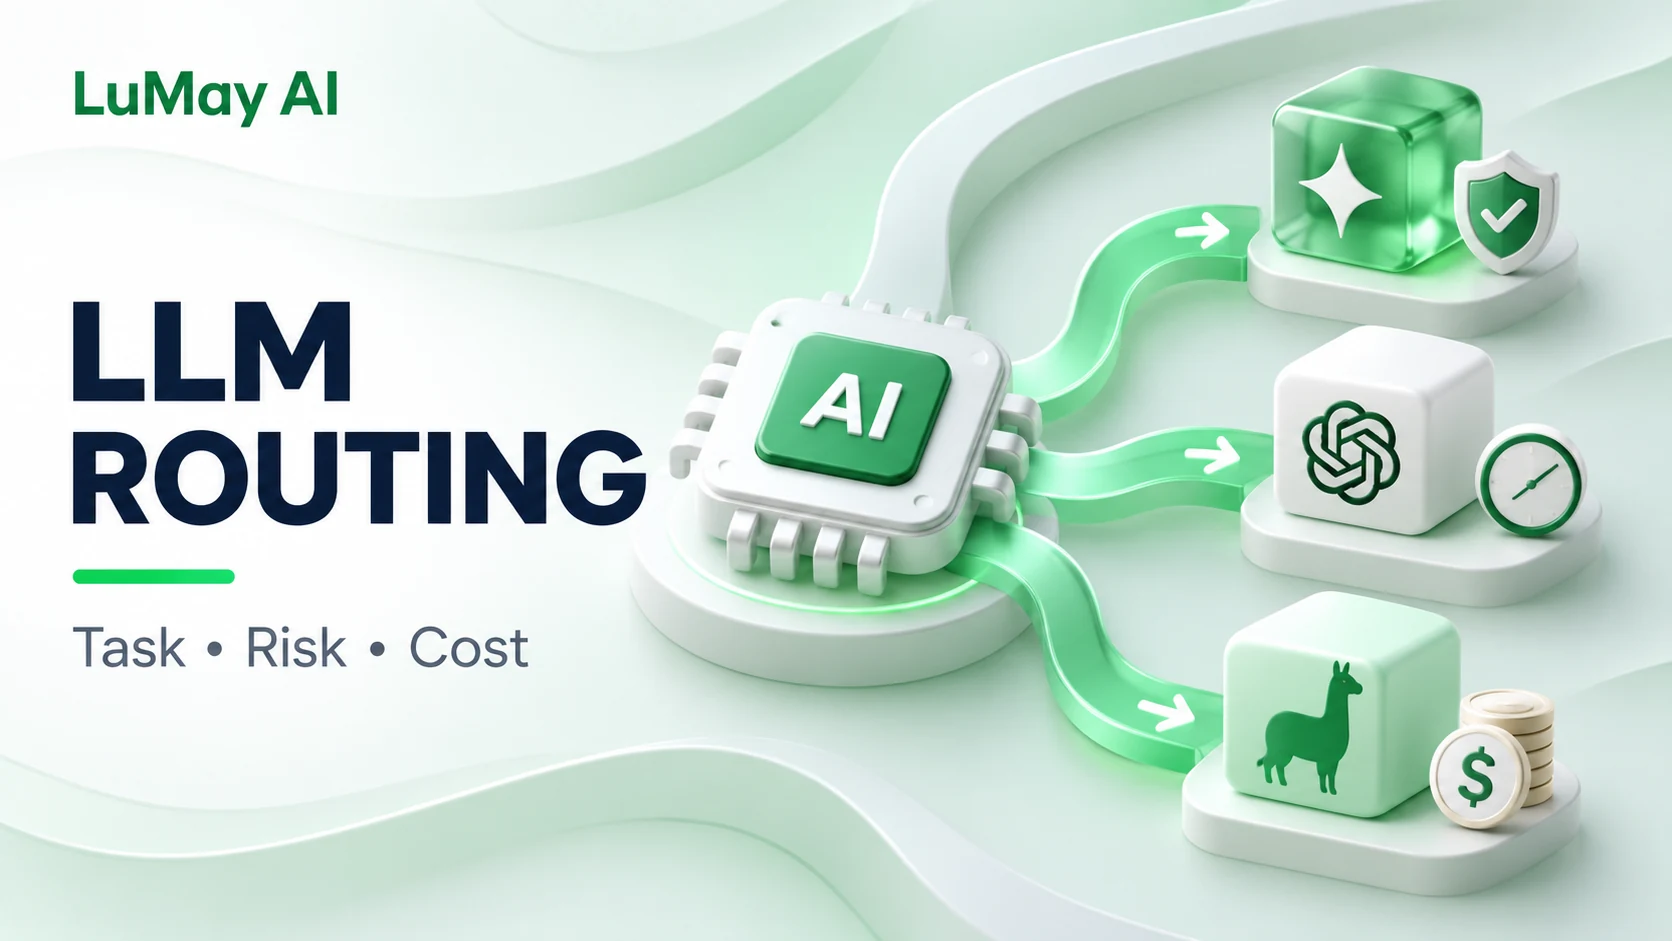
An LLM router chooses which model handles a request. The useful enterprise question is which eligible model can complete the task at an acceptable level of quality, latency and total cost.
Begin with data and capability constraints. Compare models only within that permitted set. Add fallback behavior after defining how a failed request can recover without repeating business actions or sending information somewhere unapproved.
Separate routing, fallback and escalation
| Mechanism | When it happens | Purpose |
|---|---|---|
| Routing | Before the main request | Select an eligible execution path |
| Fallback | After an availability or quality condition | Recover through another approved path |
| Escalation | When automation cannot complete safely | Obtain human review or additional information |
A second model is not always the appropriate fallback. If the source lacks a fact, a larger model cannot establish it. If a provider is unavailable, an alternative provider may have different data-handling terms.
Apply eligibility rules before cost optimization
Build an application-owned model registry. For each model configuration, record permitted data classes, deployment regions, supported interfaces, context constraints, tool capabilities, approval status and evaluation coverage.
Filter against the current request's requirements. A route that cannot meet the required residency or interface constraint should be excluded before the router compares predicted quality or price.
Keep these rules server-side and versioned. A user's request to “use the cheapest model” should not override the organization's data controls.
Choose a routing strategy that you can evaluate
Start with explicit task rules when you have a small set of well-understood jobs. For example, a classification task with a limited label set can have a different model pool from a long-document analysis task.
Use a learned or predictive router when its evaluation demonstrates value on your workload and you can investigate its errors. A complexity label alone does not establish that a selected model will answer accurately.
Amazon Bedrock's intelligent prompt routing documentation describes routing between models within a model family based on predicted response quality. It also identifies limitations, including English-prompt optimization and no adjustment from application-specific performance data. Check current model and region support before choosing that managed approach.
Define a routing decision record
For each request, retain the policy version, eligible pool, chosen configuration, task category, route reason, fallback attempts and final outcome. Store redacted metadata rather than logging sensitive prompts indiscriminately.
Use an explicit “no eligible model” outcome. Silently selecting an unapproved model makes the router's apparent availability misleading.
Measure cost per accepted task
Token price is one component. Include router overhead, failed attempts, secondary model calls, latency effects and necessary human correction. Compare workloads using the same task definition and quality gate.
Illustrative calculation: suppose 1,000 tasks use a smaller model at an assumed $0.002 per initial attempt. If 150 require a larger-model retry at an assumed $0.02 each, model-call cost is $2 plus $3, or $5. If 50 outputs still need an assumed $0.50 of human correction each, the combined amount is $30 before router, hosting and other operating costs.
These invented inputs explain the method; they are not vendor prices or LuMay results. The example shows why a low initial inference bill can coexist with expensive task completion.
Test routes against the same reference tasks
Compare an approved single-model baseline with the router. Use reviewed tasks containing ordinary requests, difficult cases and deliberately unsupported requests.
Score accepted-task rate, important error categories, end-to-end latency and cost. Break results down by task, language and data class. Count requests that exhaust the fallback chain as failures or escalations, according to the agreed task definition.
Inspect routing errors directly. Did the system select a model lacking the required context capacity? Did a short prompt contain a difficult domain question? Did a fallback produce a different output contract?
Bound fallbacks before enabling them
Set a maximum attempt count and cumulative budget. Distinguish a transient provider error from a policy refusal, invalid input, missing evidence or failed business validation.
Preserve the original request identity across recovery. If an earlier tool call may have completed, check its recorded result before another route repeats the action. Reconcile different providers' error and output formats at the application boundary.
A router should not erase the evidence that the first attempt failed. Keep both the attempted paths and the accepted outcome so operators can understand the actual cost and failure pattern.
When is routing unnecessary?
A single approved model can be the better starting point when traffic is modest, tasks are homogeneous, or router evaluation costs more than the expected savings. Improve the task definition and input quality before adding a decision layer whose behavior you cannot measure.
Write a routing policy for one bounded workload, compare it with the baseline, and expand only when the observed results justify the additional operational complexity.